Here is the question the homepage chip row has to answer: when a reader taps "agents", what should come back?
The reader's answer is easy. Everything about agents. Ours, until this month, was 3,171 articles, because the chip was the tag agents and the tag agents was attached to 3,171 rows. Two chips over sat agent, with 13,130, and agentic, with 3,972. The three overlap on only 951 articles, so a tap on the biggest of them still missed about a third of the 19,311 stories that are about agents by any fair reading. Which chip the reader saw first depended on the month: over the last thirty days agents (1,274) outranked agent (982), and over the lifetime of the site the order flips.
Nobody designed that. It fell out of how the tags are made, and fixing it turned into a question we were asked directly: would a knowledge graph help? The short answer is that a graph helps and a knowledge graph would not, and the difference between the two is the whole design.
Where the tags come from
Blackwell measured what the tag table is worth: seventeen to one against a random tag naming a real topic. This post is about why, and the why is a mechanism, not a mystery. A tag is a word the headline used. The tagger lowercases the title and abstract, drops stopwords, counts what is left, and keeps up to eight of the most frequent single words. No stemming, no phrases, no synonyms. Two copies of that script exist, one in Python and one in TypeScript, and they had drifted far enough that the same article got different tags depending on which pipeline ingested it.
Counting words buys you a table shaped like this:
| Measure (local database, 2026-09-14) | Value |
|---|---|
| Distinct tags | 93,898 |
| Tags used exactly once | 52,245 (56%) |
| Tags used more than 1,000 times | 219 |
| Tags containing a space | 0 |
The last row is the one that matters for design. Not one tag in 93,898 is a phrase. "Open source" cannot exist, so open (2,163 uses, inside the top sixty) stands in for it. "Data center" and "machine learning" cannot exist either, because data, machine and learning are stopwords or get split apart. And the reader intent we would call "what AI costs" was spread across seventeen tags, from cost (3,068) and pricing (1,991) down to finops (76) and tokenomics (18), none of which says whether the cost in question is an inference bill or a data breach.
The junk, meanwhile, was stored and ranked and then hidden at read time by four separate deny lists (439, about 452, 94 and 76 words) that had to be kept in sync by hand. Only one of the four had a test.
Would a knowledge graph help?
The term covers two different artifacts, and the real question is which one.
A knowledge graph in the usual sense is entities and relations extracted from the text: this company acquired that one, this model was trained on that dataset. It is the right structure for answering questions, and this site does not answer questions. Building one over 265,507 articles means either a language-model pass per article or an embedding pipeline, and both were off the table for a first cut by house rule: no paid per-article classification without a budget line, no new dependencies without approval.
Our problem is smaller and stricter. One reader intent has to map to one node no matter the surface form (agent, agents, agentic), the medium (an article tag, a YouTube category, a podcast manifest tag, a curated source tag) or the pipeline that wrote it. That is a thesaurus problem, and the standard model for a thesaurus is a graph with four kinds of edge:
| Edge | What it fixes | Example |
|---|---|---|
| surface form to concept | the agent, agents, agentic split | 23 spellings, phrases and framework names resolve to ai-agents |
| concept to broader concept | a chip that includes its children | tokenomics sits under cost-of-ai, which sits under ai-economy |
| concept to related concept | suggested chips, related rails | ai-agents points at mcp, ai-coding, ai-assistants, automation |
| concept to medium matcher | one node reaches every page | ai-agents names its video category and its three source tags |
A flat synonym map buys the first row and nothing else. The graph earns its name on the other three. Hierarchy is what lets "AI economy" include FinOps, GPU capex and data-center power without a reader having to know we filed them separately. Related edges are what a topic page uses to say "also: MCP, AI coding". Medium edges are what let the media hub, the homepage and a topic page all read the same node instead of three hand-paired lists. Sixty nodes with those edges fit in one JSON file. A graph database was considered and rejected on size alone; a few hundred nodes and edges do not need a server.
The alternative that almost worked
The tempting shortcut was to let the corpus build the graph itself. Tags that co-occur in the same articles are presumably about the same thing, so a pointwise-mutual-information pass over 1.58 million tag assignments should hand us the clusters for free.
For technical seeds it does. rag pulls in retrieval-augmented, chunking, graphrag, llamaindex and vector-db. gpu pulls in h100, cuda, amd and utilization. kubernetes gives you pod, keda, etcd and autoscaling. A curator could accept those lists as drafted.
For the seeds that needed the help, it does not. agentic co-occurs with commerce, another, era, isn and a run of vendor names. cost co-occurs with hidden, true, per and medication. And the long tail cannot bootstrap itself: finops had three neighbours above threshold and tokenomics had none, which is exactly backwards from what the reader needs, since the rare spellings are the ones a graph exists to absorb. The number that killed co-occurrence as a runtime is zero, the neighbour count for the tag that started the conversation. It stayed in the repo as an offline suggestion script for the curator and never became a source of truth.
Stemming everything at write time went the same way, for a reason we already had on file: the July plural merge, run once, took kubernetes down to kubernete before anyone caught it. Folding now happens only inside the registry, on pairs a person has looked at.
What sixty nodes look like
The registry is src/lib/topics/concepts.json, shaped after the one vocabulary in the repo that had already solved this problem for a smaller corpus, the 64-slug tech-tag list behind the careers page. Each concept carries a label, a blurb, its broader and related concepts, the stored tag names it absorbs, word-boundary patterns for the phrases the unigram tagger split, and its per-medium edges. One file, loaded by both the TypeScript app and the Python ingest, with one fixtures file that runs under both test suites so the two pipelines cannot drift again.
Sixty concepts absorb 4,827 tags through 1,008 patterns. Three rules did most of the work.
Word boundaries are mandatory, because substring matching is how ai ends up inside "brain".
Ambiguous bare words never qualify alone. cost, model, open, power, grid and equity need a phrase, or they need a guard.
A guard is a conjunction. cost counts toward cost-of-ai only when the same article also matched ai, llms, gpus-chips, cloud, inference or one of six other AI concepts on its own. That is the one rule a synonym map cannot express and a graph edge can.
Every concept was sampled against the database before it shipped, random titles per node, read one at a time. The bare words that misfired came out or got guarded: camera, runtime, crime, law, metadata, regression, cpu, linux, chat, power. Privacy became its own node with two parents, security and ai-governance, because a reader tapping "privacy" wants both halves and neither parent alone returns them.
The exception that tested the design came from podcasts. Episode descriptions carry show-notes boilerplate: sponsor reads, "subscribe wherever you listen", a privacy-policy link on every episode from some networks. Run the registry over the raw text and 91% of 102,678 episodes got a concept, which sounds like coverage until you look at where it came from. media-entertainment alone held about 40,000 rows, mostly from the word "podcast" in the footer, and privacy was matching the legal link. Thirteen boilerplate patterns are stripped before classification now, "privacy policy" is excluded from the privacy pattern, and coverage fell to 82%. The lower number is the honest one.
Where the reader meets it
On the homepage the chips are concepts now, counted over the last thirty days with a source-diversity gate like the tag heatmap's: at least five sources, none of them supplying more than 65% of the uses. A chip has to be something the field wrote about, not one prolific blog's vocabulary. A tap on "AI agents" runs ?topic=ai-agents, and the old ?tag=agents links resolve through the same registry. Cards lead with the concept label and keep the raw tags behind it.
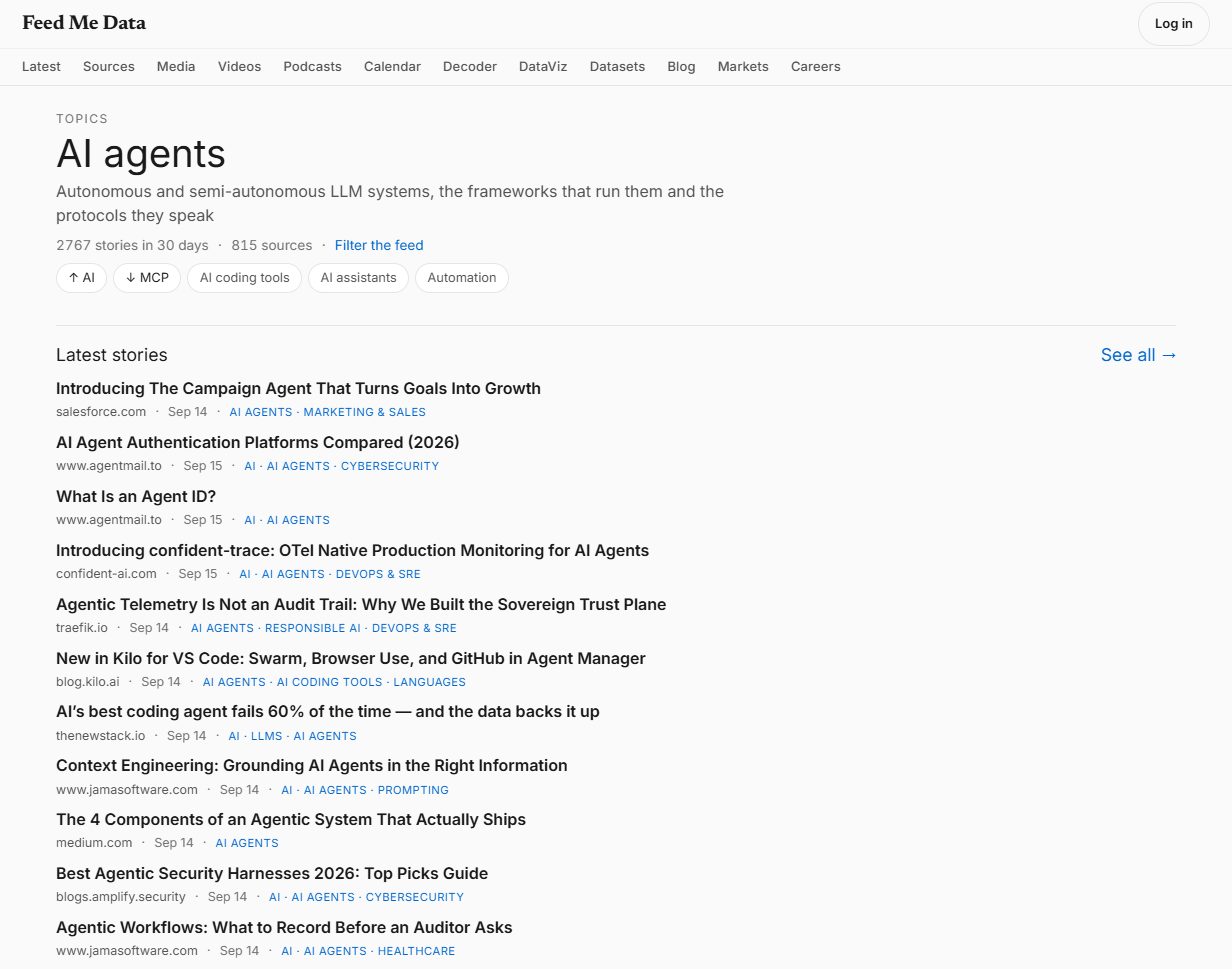
Each concept has a page at /topics/<id> that pulls articles, videos, podcasts, episodes and the sources tagged for that subject through the medium edges, which is the crosswalk the media hub deferred in August. Related videos pivot on the watched video's concepts instead of YouTube's own category, where "related" used to mean "also filed under Technology". The four deny lists became one stoplist of 503 words.
Two implementation notes, because the numbers changed decisions. Memberships live in their own tables (389,683 article rows and 225,730 episode rows on the local copy, covering 73% of articles and 82% of episodes) rather than mixed into the tag table, so counts stay clean. And the thirty-day chip aggregate took 15 to 20 seconds in SQLite on the request path, which would have frozen every page the way an earlier query did; it runs on the DuckDB sidecar instead, with a cache warmed at boot. A topic filter that took 22 seconds for quantum takes half a second.
The residue, priced
Patterns cannot read intent out of a headline with no keyword in it. "The bill came due" is a cost-of-AI story that no regex will ever catch. For that residue, and for the whole corpus once, we priced a language-model pass instead of pretending the registry was complete.
Claude Haiku 4.5 through the Batch API costs $0.50 per million input tokens and $2.50 per million output tokens, which works out to about $0.00025 per item at our sizes: roughly $92 to label the backlog once and $5 to $10 a month after that. The labeler refuses to submit a batch that would push the month past a $25 cap, meters every batch into the same usage log the FinOps page reads, stores its rows with a confidence score and a source of llm, and never overrides a registry match. It ships behind a switch, and the first full-corpus batches run by hand. A local model was tried too; the laptop's GPU had 3.4 GB of its 8 GB held by desktop applications, and that experiment is waiting for a quiet afternoon.
A tag is a word the headline happened to use. A topic is a promise about what a tap returns. The first can be counted by a script. The second has to be curated, and sixty is a number one person can curate.